Jev Prunes Agent Context Instead of Rewriting It
Most agents summarize old context with another LLM pass. Jev does something different: it scores relevance and lets host code delete stale tool calls, leaving surviving text exactly as it was. Fast-jev-compaction never rewrites history; it asks Jev two yes/no questions per tool call, then drops or truncates blocks that score below a threshold. What remains is verbatim. The awesome-jev catalog warns that preserving retained text verbatim does not prove that omitted history was unnecessary. A probability is not proof.
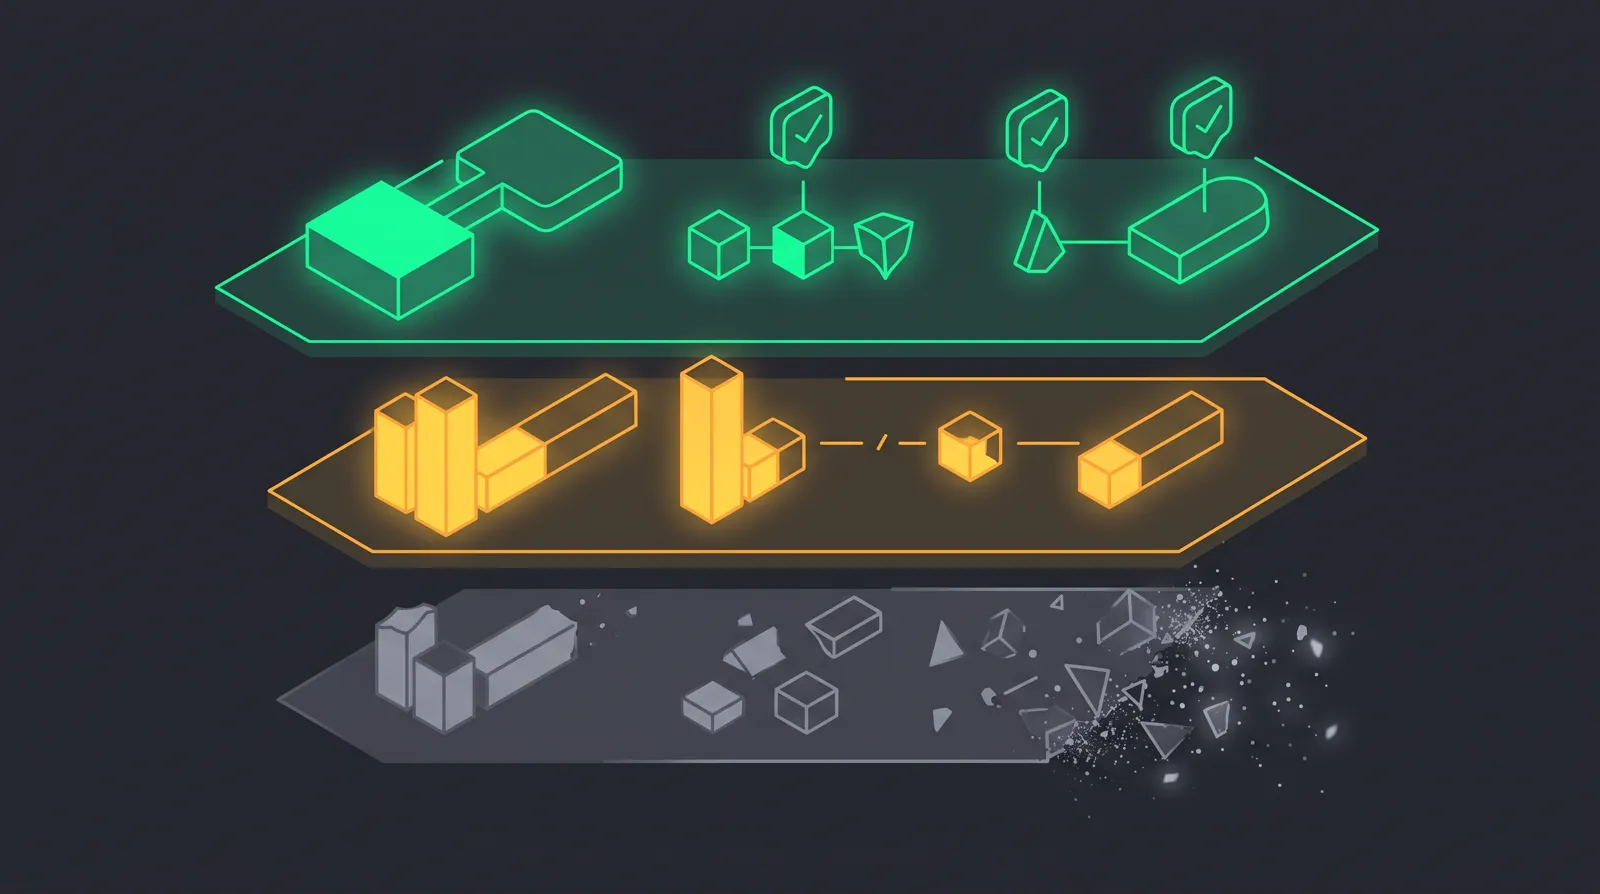
Jev’s role in compaction is narrow: answer typed Noul questions about each span. Host code owns pins, thresholds, truncation heads, and fallback policy. The failure mode differs from summarization. A typed System One model cannot invent a file path that was never there. It can be wrong about relevance.
Pruning Pattern: Ask, Threshold, Act
The pattern is straightforward. Ask Jev (or another System One model) a Noul question: “Is this tool result still relevant to the current task?” Jev returns a probability. Code compares that score against a threshold (typically 0.5) and acts: keep, truncate, or drop.
Fast-jev-compaction (tamaratran) is a Claude Code plugin and npm library. It asks two Noul questions per non-pinned tool call: should we keep the call? Should we keep the result verbatim? Three tiers fall out against one keepThreshold (default 0.5). If keepResult clears the threshold, both call and result stay. Else if keepCall clears it, the call stays but the result truncates to truncateHeadChars (300 by default) plus a note. Otherwise both call and result disappear. Pins are simple: the first user message plus the newest preserveRecentMessages (default 6) stay untouched. State is fitted to maxStateTokens (25,000); request batches stay under maxRequestTokens (30,000). If Jev errors or reduction falls short, the hook falls back to Claude Code’s built-in summary.
Recovery is a tool re-run. The README is blunt: “A probability is not a proof that a result is safe to delete. The assistant can always re-run the tool.”
Fast-dev-compaction (leonaaardob) ports the same engine idea to OpenAI Codex, which cannot replace history like Claude hooks. Instead, Codex injects kept spans as additionalContext after the native summary runs. The author’s README posts a warning: production use is not recommended. The critique, drawn from Theo (@t3.gg), is that pruning on probability misunderstands compaction. Models trained on their own compaction flows discard reasoning traces that never surface over API. Editing history triggers cache rewrites. The tool is idea documentation, not shipping code. For Day 5, it supplies nuance: even a port has doubts.
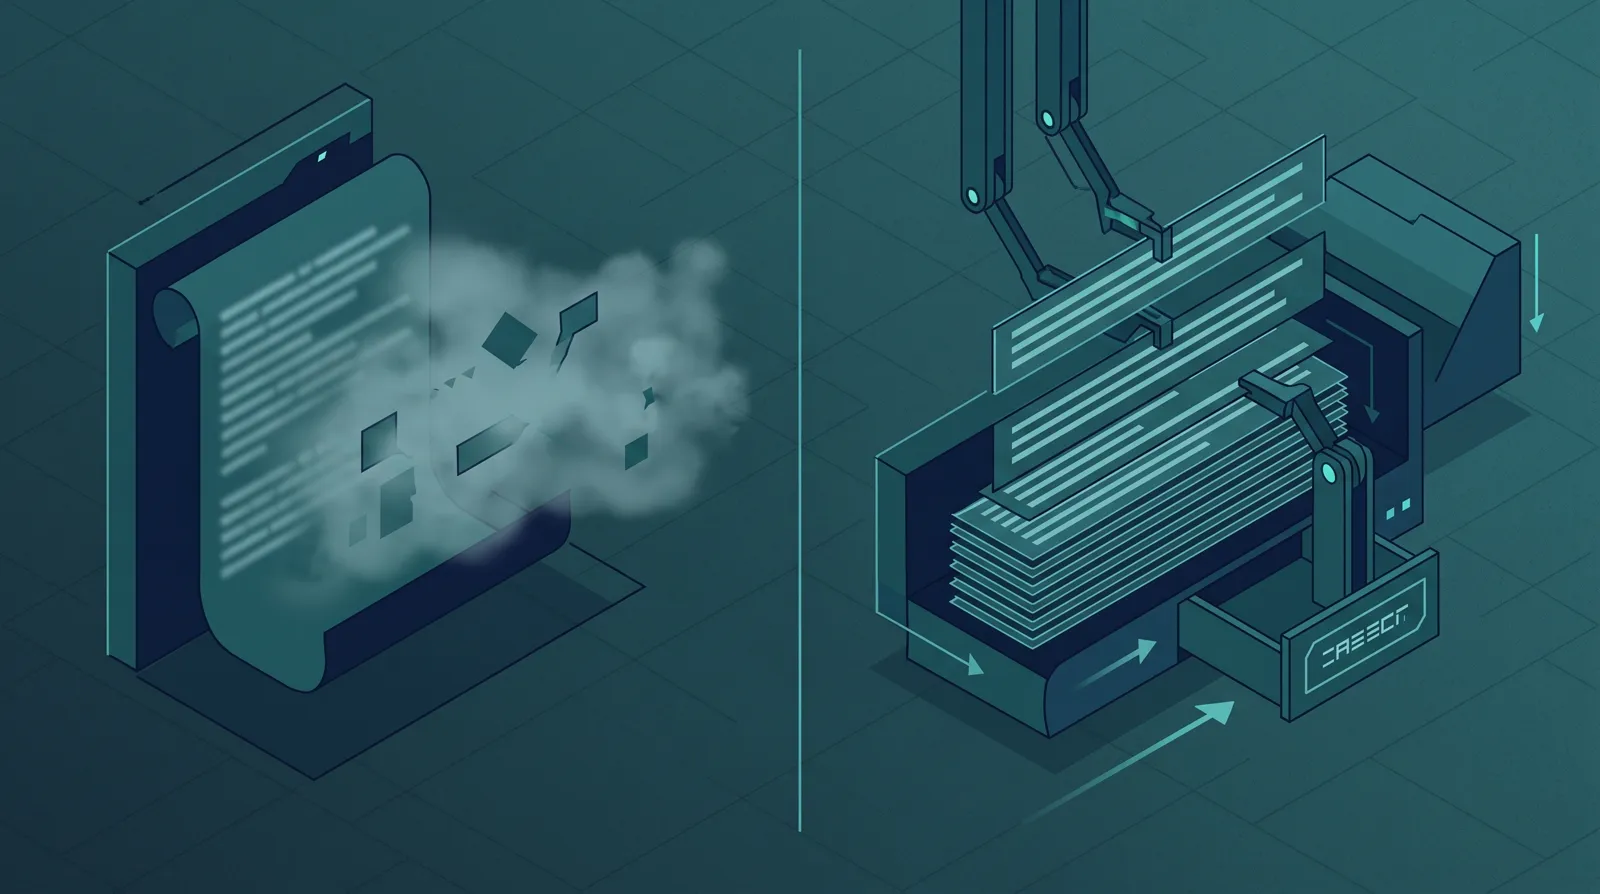
Winnow: Admit-Time Sieve
Winnow (GhalebDweikat) judges large Read, Bash, or Grep results before they enter Claude Code context. It splits output into roughly 25-line blocks, then asks one yes/no relevance question per block (default judge: Jev). Confident-no answers (below a DROP threshold, default 0.1) become three-line stubs plus a local cache key under ~/.winnow/cache/, with an optional cheap summary. Recall the full block later via winnow_recall.
Safety policy: error outputs never hide. The uncertain band between DROP (0.1) and KEEP (0.5) stays verbatim. The author recommends shadow mode for a week to watch what would have been pruned. On 97 hand-labeled cases out of 300, the author measured roughly 5% of text hidden clean below 0.1 with the structured question set (self-reported; not independently retested). Winnow also ranks memory files at prompt time.
The admit-time approach means Winnow runs once per tool output, not over accumulated history. Stubs are visible; recovery is explicit (call winnow_recall with the key). The trade is immediate: you pay Jev judging cost up front instead of deferring until context pressure forces a compaction pass.
Yoshi: Proxy POC with Candid Metrics
Yoshi (compozy) is a local proxy for Claude Code and Codex. Jev judges spans above a size gate; code applies validated omissions while preserving protocol; the provider response streams unchanged. The author is candid: this is an experimental proof-of-concept heading into CompozyOS. Current v12 trials ran slower than baseline. A Fable diagnostic session showed roughly 34% accumulated input reduction; a Sonnet mixed session showed near 0% savings. Combined costs are unknown because Jev receipts were incomplete during the trial. Candidate spans (including Write, Edit, and Bash source) go to TypeSafe via Vercel AI Gateway. There is no zero-data-retention (ZDR) option on that path.
Do not sell Yoshi as proven savings. Its value is honest reporting: a POC may reduce tokens yet add wall-time, or produce no reduction at all depending on session shape. Stars on GitHub do not equal correctness or efficiency.
What Jev Selects vs What Code Must Keep
Jev answers typed Noul probabilities. Host code decides policy. Fast-jev-compaction pins recent messages and the opener; Winnow pins error outputs and the uncertain band; Yoshi gates spans by size. None of them prune user instructions or error paths.
The compaction essay on aiskill.market summarizes the failure mode: a typed judge cannot invent what was never there, but it can be wrong about relevance. Fast-jev’s README repeats it: the assistant can re-run the tool. Winnow offers winnow_recall with the cache key. The safety net is retrieval, not infallibility.
Pruning is not summarization. Summarization asks an LLM to rewrite context into fewer tokens; the original words disappear. Pruning asks a judge which spans matter, then deletes the rest. Surviving text stays verbatim, in order. The risk shifts from rewrite errors (hallucinated paths, merged instructions) to selection errors (dropping a span that turns out to matter three turns later).
TypeSafe introduced Jev as System One for decisions below the generation threshold. Context compaction is one such decision: prune or keep, not rewrite. The model shape is deliberate. The tools above share that shape. Fast-jev, Winnow, and Yoshi all ask Jev (or a peer System One model) typed yes/no questions, then act on the score. They differ in when they ask (per call, per block, per request), where they hide omissions (delete from history, stub with recall key, omit from proxy payload), and how they recover (re-run, explicit recall, none yet).
The TypeSafe Jev hub covers the manifesto and Doom/Wikirace demos. Day 4 covered guardrails: is-malicious, jev-guard, Canny, wakegate. Day 5 is compaction: delete stale calls, keep survivors verbatim. A probability is not proof that dropped context was safe to forget. But when the agent can re-run the tool or recall the cache key, the cost of being wrong is a round trip, not a hallucinated answer.
