Noul meaning, in one line: Noul is a TypeSafe question type. You hand Jev, TypeSafe’s System One model, a yes/no proposition, and it returns the probability of “yes” as a number from 0 to 1. Noul is not a chat model, and it is not a data type in a general programming language.
In the TypeSafe API that Jev answers, Noul is one of three question primitives beside Choice and Score. A Noul answer is deliberately small, so application code can test a threshold without extracting a verdict from generated prose.
If you arrived here through the wider AI topic, the AI hub has the surrounding coverage. The TypeSafe Jev and System One guide explains the larger decision-model argument; this tutorial stays with the programming surface.
Noul in one line of code
The smallest useful shape is one Noul against a tiny state object:
from typesafe_sdk import Noul, TypeSafeClient

with TypeSafeClient() as client:
    response = client.system_one(
        state={"ticket_message": "My flight was cancelled. Can I get a refund?"},
        questions={
            "refund_requested": Noul(
                instructions="Does `ticket_message` explicitly request a refund?",
            ),
        },
    )

p_yes = response.answers["refund_requested"].noul  # float in [0, 1]
That return value is the probability of yes under the question and state you supplied. Your code decides the threshold. The larger three-primitive example further down shows Choice and Score in the same call.
What Noul means in AI and Jev
The name is unusual. The behavior is not. Give Jev some state and a proposition such as “Does this message request a refund?” A Noul question returns a single noul value.
- A value near 1 means the supplied evidence strongly favors yes.
- A value near 0 means it strongly favors no.
- A value near 0.5 means the model is split between the two readings.
That middle value does not mean “medium.” There is no medium category in a yes/no proposition. If the real question is “How severe is this bug?”, the shape is wrong for Noul. That calls for Score.
People also search “Noul data type.” Fair label for the API surface, but the meaning is still the yes/no probability question above. In Jev, Noul is a typed question and answer primitive, not a built-in scalar like a Python bool or float, even though the returned probability is numeric. “Noul programming” is not a separate language either. The term belongs to Jev’s constrained decision interface.
Noul also has no separate confidence field. With only two outcomes, the single number already describes the whole distribution, so the probability is the signal (the Jev confidence post covers how Choice and Score summarize theirs). A result of 0.93 says the model assigns a 93 percent probability to yes under the question and state you supplied. It does not certify that the proposition is true.
Noul vs boolean: why a probability, not true/false
A search for “noul vs bool” or “noul boolean” usually means this: why doesn’t Jev just return true or false?
A boolean forces a hard cut. The model would have to pick a side even when the evidence is thin, contradictory, or missing. Noul keeps the continuous answer: a float from 0 to 1. Application code then owns the policy. Refund review at 0.9, human handoff between 0.4 and 0.7, auto-reject below 0.2. Those cutoffs live in your repo, where you can change them without rewriting the question.
So Noul is not a replacement for Python’s bool. It is a typed yes/no question in the TypeSafe API whose payload is a probability. Once you threshold that number in code, you get a boolean for your branch. The docs for the shape are on docs.typesafe.ai/primitives/noul.
Choice, Score, or Noul?
The fastest way to pick a Jev primitive is to look at the branch your code needs next.
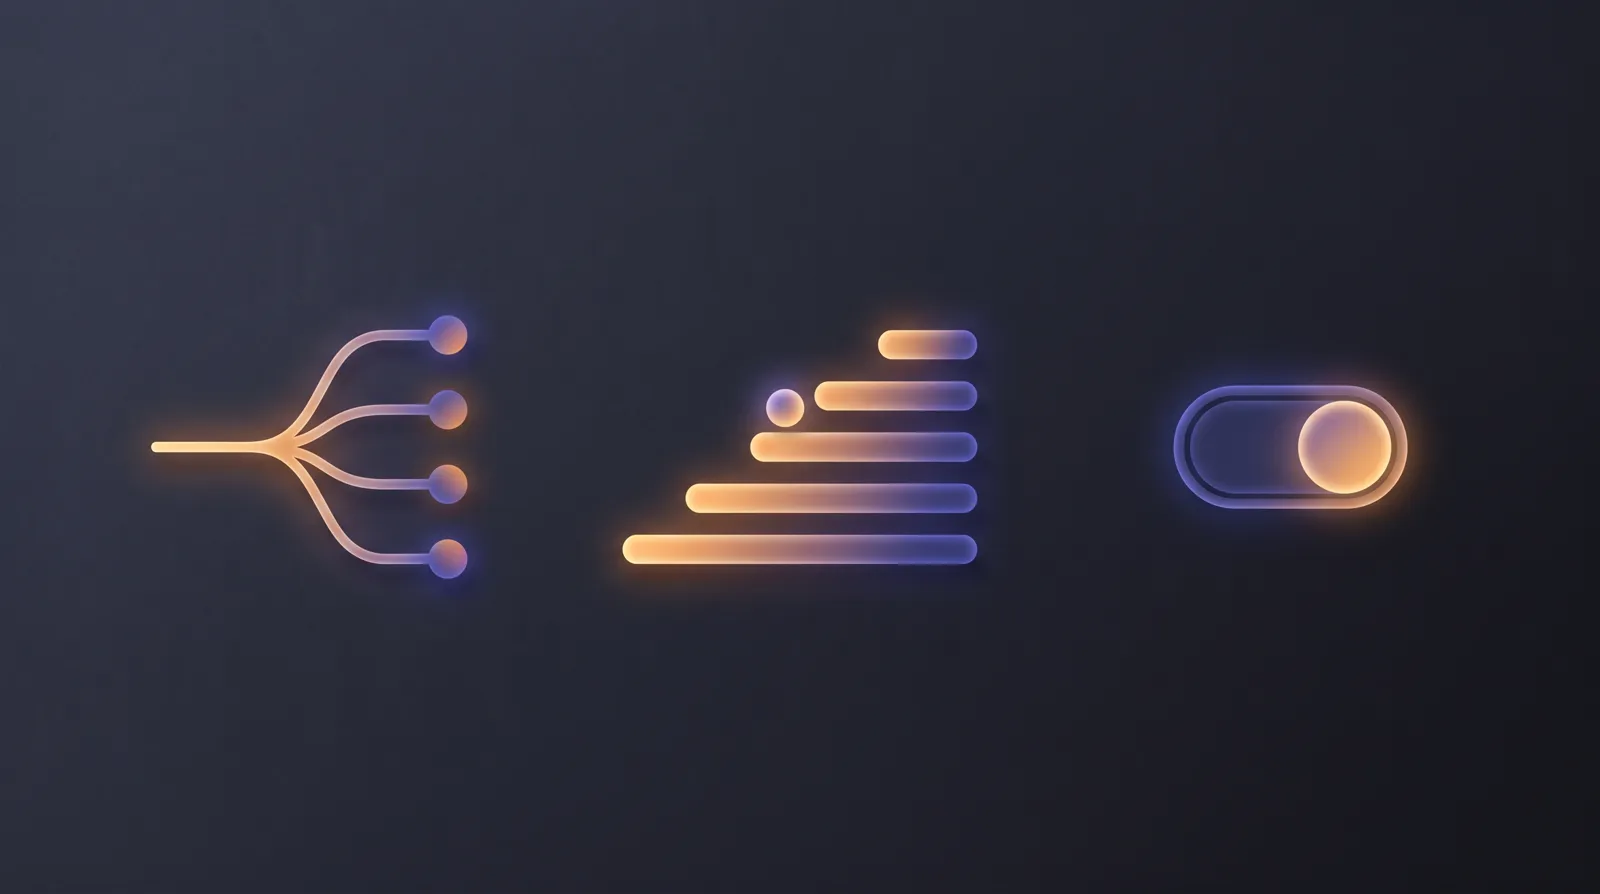
- Choice selects one member of a closed, unordered list.
- Score places the evidence on ordered levels you define.
- Noul estimates the yes probability of one crisp proposition.
Suppose a support ticket says, “My flight was cancelled. Can I get a refund?” The destination queue might be a Choice among billing, rebooking, and other. The customer’s frustration fits a Score rubric. Whether the message requests a refund is a Noul.
All three are constrained questions, but they constrain different things. Getting the shape right matters more than inventing a clever prompt.
Choice picks from a map you supply
Choice works when the possible routes are known before the call. Support department, document class, request intent, and programming language are common cases.
A Choice answer contains the selected choice, a probabilities distribution over every option, and a confidence summary. Your code can feed the selected key into a switch without cleaning up free text.
The closed list creates a responsibility. If production input can sit outside your named categories, include other or none_of_the_above. Otherwise the model must choose the least-wrong option. A valid key can still be a bad classification.
Score measures position on an ordered scale
Score is for severity, frustration, skill, risk, or another judgment with ordered levels. Jev returns a numeric position, which may fall between two labels, along with the legend, level probabilities, and confidence.
The rubric carries most of the quality. “Low, medium, high” hides the policy in three vague words. “Cosmetic issue,” “workflow blocked but a workaround exists,” and “data loss or security exposure” gives reviewers a scale they can test against labeled examples.
A Score becomes useful after code maps ranges to an action. Set those ranges from your own cases and error costs. The pretty shape of one response is not calibration.
Noul asks one proposition at a time
Good Noul questions can be answered yes or no from the supplied state:
- Does
ticket_messagerequest a refund? - Does
ticket.messages[0].textcontain personally identifiable information? - Does the resume state that the candidate used Python in paid work?
Compare the last question with “How skilled is the candidate in Python?” The first checks whether a specific claim is supported. The second asks for a graded judgment and should be a Score.
Two more rules from the Noul documentation save a lot of debugging. Ask one condition per Noul: “Is the customer angry and asking for a refund?” forces the model to judge both at once, so ask two Nouls and combine them in code. And phrase the question so a high value means yes. “Is the message free of personal data?” inverts the meaning, and someone reading the threshold later will get it backwards.
Keep the proposition narrow enough that a knowledgeable reviewer could make the judgment quickly from the same evidence. “Analyze the account, interpret the refund policy, pick the best remedy, and write a reply” is not one Noul. It combines evidence retrieval, policy logic, a decision, and text generation. Split those jobs, then join the results in code.
The anatomy of a Jev question
The TypeSafe primitives documentation describes four pieces that recur across these questions:
- an ID, such as
refund_requested, which your program uses to retrieve the answer; - a type:
choice,score, ornoul; - instructions containing the actual judgment;
- and, when the type needs them, criteria defining options or levels.
The ID is for your application. It is not a substitute for instructions. Calling a question policy_match does not tell the model which policy, which claim, or which part of the state should be compared.
Noul usually needs no list of options because yes and no are already implied. Optional criteria, given as true and false descriptions, can still sharpen the boundary when a term has a domain-specific meaning. If “refund request” includes chargeback threats but excludes a request for store credit, write that rule where the model can see it.
Working code: one state, three question types
A single System One call can mix Choice, Score, and Noul. Here is the support-ticket shape using TypeSafe’s Python SDK:
from typesafe_sdk import Choice, Noul, Score, TypeSafeClient

state = {
    "ticket_message": "My flight was cancelled. Can I get a refund?",
    "refund_policy": "Cancelled flights qualify for a full refund.",
}

questions = {
    "request_type": Choice(
        instructions="What is the main request in `ticket_message`?",
        criteria={
            "refund": "The customer wants money returned.",
            "rebooking": "The customer wants another flight.",
            "information": "The customer only wants information.",
            "other": "The request does not fit the other options.",
        },
    ),
    "frustration": Score(
        instructions="How frustrated is the customer in `ticket_message`?",
        criteria=[
            "Calm and neutral.",
            "Concerned but civil.",
            "Very angry or using strong language.",
        ],
    ),
    "refund_requested": Noul(
        instructions="Does `ticket_message` explicitly request a refund?",
    ),
}

with TypeSafeClient() as client:
    response = client.system_one(state=state, questions=questions)
The state is sent once. Every question sees that state, runs independently, and returns under the ID chosen by the application.
Independence is easy to miss. The answer to request_type does not become hidden context for refund_requested inside the same call. If question B truly depends on answer A, receive A in code, fetch or rebuild whatever B needs, then make the second call. When both judgments can be made from the original state, keep them together.
Use a field path when the state gets large
A production state object may hold a message thread, order, payment records, policy text, and internal notes. “Does the customer request a refund?” leaves room for the model to inspect the wrong passage.
Name the relevant field path in backticks:
Does `ticket.messages[0].text` request a refund?A policy check can point to two places:
Does `refund_policy` cover the duplicate charges in `order.charges`?The path lives inside the instruction text. Think of it as an address for the model to read, not a query your code runs. The benefit reaches beyond the model: an engineer reviewing the question can see which evidence is supposed to control the answer.
Batch independent questions before making another call
System One evaluates questions in parallel. When several judgments use the same state, one request avoids sending a large document again and again.
The TypeSafe parallel-questions cookbook asks 13 questions (8 Noul, 2 Choice, 3 Score) about a pinned copy of the Wikipedia GDPR article, roughly 54,000 characters. Run five times each way on jev-1.12, the single batched call came out 12.2 times cheaper and 10.0 times faster than 13 one-question calls, with the same answers. The primitives overview still quotes an earlier run of the same cookbook at 11.5x and 9.6x. Either way, those ratios belong to that document and that setup. The speed figure also sums the 13 latencies as if the calls ran back to back.
The underlying reason is less dramatic than the ratios. One long input upload usually costs less than repeating the same input 13 times. Sequential calls also pay 13 network round trips. Concurrent requests narrow the wall-clock gap, but repeated input tokens remain.
TypeSafe calls the related pattern speculative fan-out: include every independent question the program may need, then ignore answers that are irrelevant to this case. A ticket can carry a department Choice, a refund-intent Noul, a frustration Score, a PII Noul, and a bug-severity Score in one request. If the ticket is not a bug report, discard the severity answer.
Do not batch a real dependency merely to save a call. If the first answer decides which database row to fetch or which options the second Choice may contain, two stages are honest and easier to inspect.
Turn probabilities into policy in code
Jev produces constrained judgments. It should not quietly own the business policy around them.
For ticket priority, ask separate Score questions about business impact, frustration, and evidence quality. Normalize the outputs and apply weights in code. When the support policy changes, the changed coefficient is visible in a diff instead of being buried in a larger prompt.
Noul naturally becomes a gate. Assume the request also carried a second Noul, policy_supports_refund, asking whether refund_policy covers the case:
answers = response.answers
refund_requested = answers["refund_requested"].noul
policy_ok = answers["policy_supports_refund"].noul

if refund_requested > 0.85 and policy_ok > 0.90:
    queue_for_refund_review()
else:
    send_to_human()
The numbers above are examples, not Jev defaults. TypeSafe’s own advice is to start at 0.5 when a false yes and a false no cost the same, raise the bar when a false yes is expensive (a refund, a page to on-call), and lower it when missing a true yes hurts more. Values stuck in the middle can go to a person. Pick the final cutoffs with labeled, production-like cases and measure both error types separately.
A typed answer can still be wrong
Constrained output fixes an interface problem. It does not grant factual certainty. Choice can select the wrong allowed key, Score can overrate a heated phrase, and Noul can assign 0.9 to a mistaken reading.
Before a result triggers payment, account closure, data deletion, or another hard-to-reverse action:
- run evals on production-like data;
- track both kinds of classification error;
- keep deterministic policy and permission checks;
- provide a human or safe fallback path;
- pin the model and provider version used by the tested workflow.
The clean mental model is enough: Choice gives code a branch, Score gives it a position, and Noul gives it the probability of yes. TypeSafe’s System One supplies those judgments. Your application still decides what they are allowed to do.
Also on Medium: Write Questions a Machine Can Answer.

4 comments