TypeSafe Jev delivers System One decisions in 70-500 milliseconds end-to-end. That’s the listed latency range from TypeSafe’s launch post, measured often from US West Coast servers. Frontier LLMs on comparable System One-shaped queries take 3 to 329 seconds. The Register’s side-by-side demo clocked Jev at ~0.114 seconds versus GPT-5.6 Terra at ~8.566 seconds for the same decision.
That’s not a benchmark trick. It’s architectural.
⚡ Parallel sampling: one query, many answers
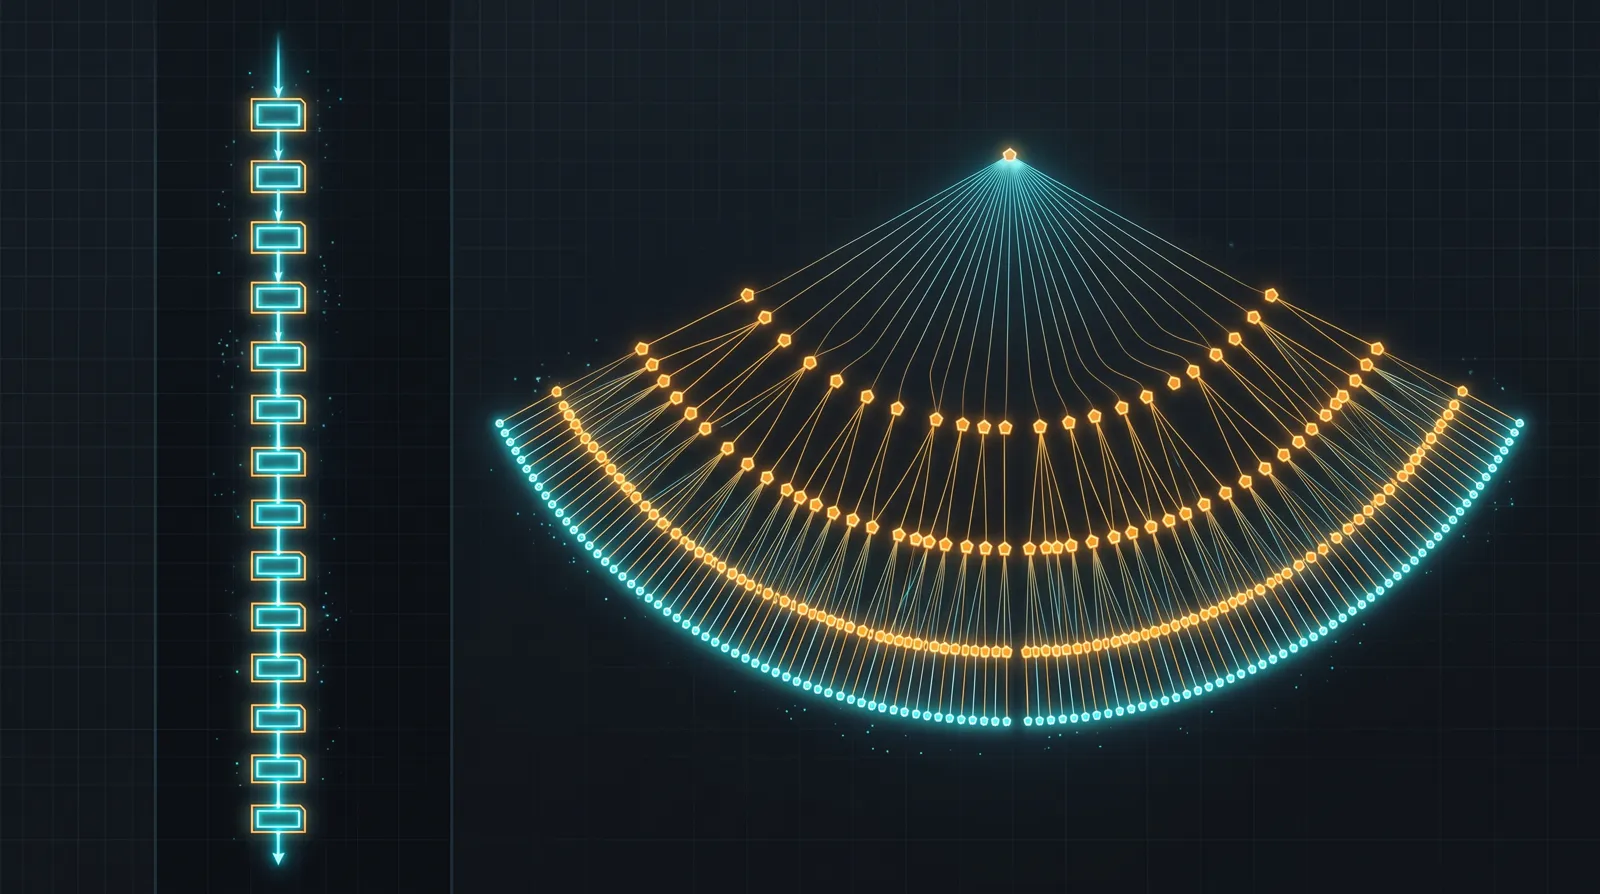
Jev speed comes from its sampler. LLMs generate tokens sequentially, one after another, waiting for each token before producing the next. You ask one question, you get one string, and the model spends time building that string character by character.
Jev doesn’t build strings. It evaluates all questions in a single forward pass. When you send state and typed questions (Choice, Score, Noul), Jev computes probabilities for every answer candidate in parallel. Adding ten more questions to your request barely changes response time. TypeSafe docs spell it out: “Every question is evaluated in parallel… Adding questions barely changes the response time.”
This is a foundational difference. Autoregressive token generation is fast now, but it’s still sequential. Parallel sampling is concurrent by design. When your consumer is code making runtime decisions, not a chat UI streaming explanations, that concurrency becomes your latency budget.
If you’re routing traffic, picking a cache key, or deciding whether to escalate a suspicious request, you don’t need a paragraph. You need Choice A or Choice B. Jev gives you that choice with a probability and confidence interval, and it gives it to you in tens or hundreds of milliseconds.
💵 Price card: $0.042 per million input tokens, output free
TypeSafe lists Jev at $0.042 per million input tokens. Output is free. OpenRouter’s Jev-1.13 page mirrors the same pricing: $0.042 / $0 per 1M. Vercel AI Gateway also lists $0.042 per million input, with a time-boxed promo (free on Gateway until September 25, 2026).
You pay for what you send. State tokens, question text. The answers are too cheap to meter.
Compare that to frontier LLMs. Input pricing often starts at $0.20 per million tokens and climbs to $10 or more for the largest models. Output costs roughly five times input. When you’re generating paragraphs of reasoning, those output tokens add up. When you’re generating typed decisions, they don’t exist.
TypeSafe is candid about sustainability. They can’t yet prove the price isn’t subsidized. Their expectation: prices fall over time, not rise. But the published list price is $0.042 per million input tokens, and that’s what you can plan around today.
For context: if your System One workflow processes 10 million input tokens a day through Jev, you’re looking at about $0.42. The same workflow through a high-end LLM wrapper, billed on both input and output at 10× to 100× the rate, lands in a different budget tier entirely.
📦 Fan-out: ask many questions once
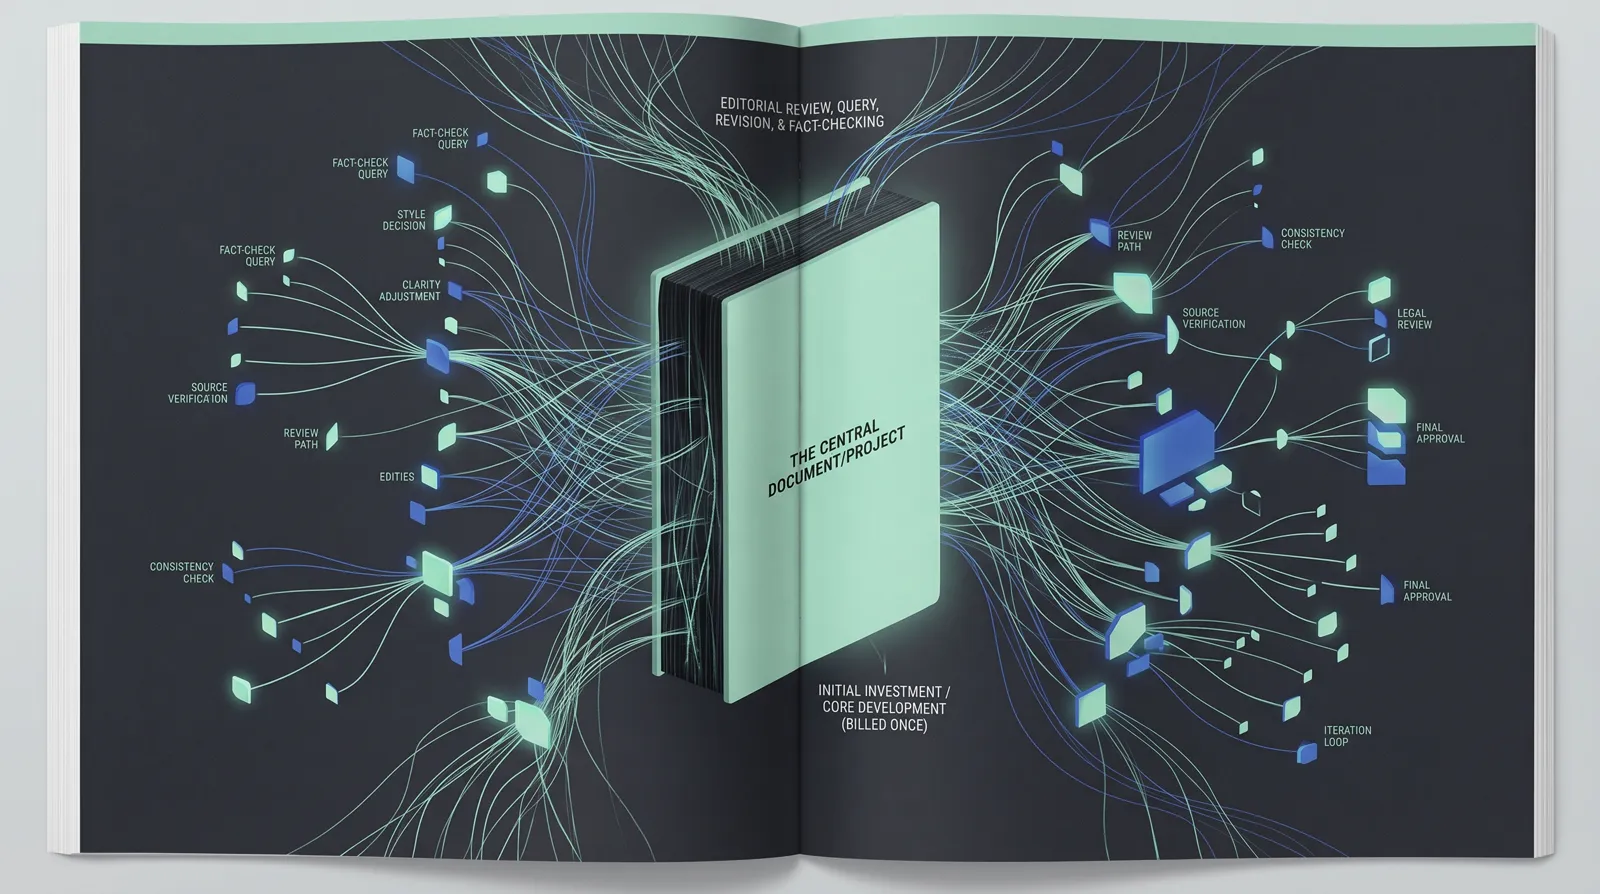
Parallel evaluation has a practical cost lever. State is ingested once per request. Many independent questions can share that state.
TypeSafe’s cookbook-style testing batched around 13 questions against the same state. Separate sequential calls would re-bill the state for every question. The batched approach came out roughly 11.5-12.2× cheaper and 9.6-10× faster than separate calls. Those figures vary slightly across TypeSafe’s published summaries, but the order of magnitude holds.
Two caveats. First, concurrent calls can shrink the latency gap if your client can fire requests in parallel. They don’t shrink the cost gap. You’re still re-billing the state every time. Second, TypeSafe is the source for the ~11× / ~10× cookbook numbers. Reproduce this on your own workflows before you budget around it.
If your state is a few kilobytes of context and you’re asking one question, batching won’t move the needle. If your state is a 20,000-token document and you’re asking ten decision questions about it, the savings compound quickly.
Fan-out is not a magic multiplier. It’s a structural advantage when your problem shape fits: shared context, many independent decisions.
📉 Pareto nuance: 193.6× and 444.6× are ceiling claims
TypeSafe’s homepage and workflow evals cite 193.6× faster and 444.6× cheaper than LLM System One wrappers. Those numbers come from TypeSafe’s own capabilities team running workflows on Jev versus structured wrappers around frontier models (averaging Astra and Fable).
The launch post calls these results the higher end of real-world gains. Why? The workflows were designed by TypeSafe engineers who know Jev’s strengths. The reference models were forced through structured output wrappers, which adds overhead. And the baseline is an average of large external models, not the fastest or cheapest option you might pick if you controlled the stack.
These are valid workflow evals. They’re not guarantees. Your mileage will vary depending on question complexity, state size, network latency from your region, and how well your problem maps to Choice / Score / Noul primitives.
The Register demo is a single snapshot: one question, one state, one network path. It showed ~75× speed advantage over GPT-5.6 Terra. OpenRouter marketplace data lists Jev’s P50 latency around 0.26 seconds, but that’s a provider snapshot, not a TypeSafe SLA.
If you’re evaluating Jev, measure it yourself. The 193.6× and 444.6× ceiling claims tell you what’s possible on TypeSafe’s own workflows under ideal conditions. Your production ceiling will depend on your stack, your state size, and your latency tolerance.
The honest Pareto framing: Jev is faster and cheaper than LLM wrappers on System One workloads, often dramatically so. The exact multiple depends on your setup. Test before you promise UI SLAs to your users.
What this means for System One routing
Speed and cost compress the decision boundary. When a System One query costs $0.042 per million input tokens and returns in 70-500 milliseconds, you can afford to route more traffic through it before escalating to a slower, costlier model.
Day 2 covered confidence intervals and RLCD training. When Jev returns a Choice with wide uncertainty, you escalate. When it returns a tight confidence interval, you act. The speed and cost numbers make that escalation hierarchy practical at scale.
Next up: Day 4 will cover agents and guardrails. How System One decisions fit into multi-step workflows, and where Jev hands off to other tools. More at the Jev hub.
