Jev is now callable through OpenRouter, Vercel AI Gateway, and Cloudflare Workers AI. TanStack AI can put all three behind the same decide() call. That makes access easy; it does not turn every AI task into a Jev task.
This final installment in the seven-part Jev series maps the routes into the model, the open projects rebuilding parts of the idea, and the cases where a language model should keep the job.
Three gateways, three slightly different doors
OpenRouter gives Jev its own API surface. The model is typesafe/jev-1.13, with ~typesafe/jev-latest as the moving alias, but it does not run through chat completions. A request goes to the alpha Decisions API at POST /api/alpha/decisions with model, state, and questions. In the @openrouter/sdk, the matching call is openrouter.alpha.decisions.create().
That distinction can prevent a failed integration. An existing OpenRouter key works and no TypeSafe account is required, but an OpenAI-compatible chat client will not understand this endpoint. OpenRouter lists a 32K context window, $0.042 per million input tokens, no output-token charge, and 0.23 seconds P50 latency on its model page. Pin typesafe/jev-1.13 to keep the model version fixed during a test. Use the alias only when an automatic model update is acceptable.
Vercel takes a framework-shaped route. AI SDK 7.0.105 added experimental_evaluate, called with the model ID typesafe-ai/jev. Its Choice, Score, and Boolean questions correspond to Jev’s Choice, Score, and Noul shapes. The result is still a typed decision with probabilities rather than prose.
The Gateway layer adds operational controls. Vercel’s launch note says Zero Data Retention and No Training can be enabled per request; calls also flow into Gateway logs, custom reports, and budgets. Teams already using the TypeSafe client have another migration path: change its baseURL to https://ai-gateway.vercel.sh/typesafe and keep the existing systemOne calls. A language-neutral HTTP client can instead use POST /v1/evaluate.
Cloudflare is the shortest route when the application already runs as a Worker. Bind Workers AI and call:
env.AI.run('typesafe/jev', { state, questions })
The Cloudflare model page documents Noul, Choice, and Score, and its examples currently return jev-1.13.0. A REST request wraps the same payload inside input. Pricing should be checked in the Cloudflare dashboard rather than copied from another provider. If exact TypeSafe SDK behavior or explicit version pinning matters more than Worker proximity, use the direct service instead.
The three routes reach the same kind of decision model. Authentication, model IDs, request wrappers, observability, and version controls differ. Record all five in an eval report. “We tested Jev” is too vague to reproduce.
TanStack AI is the integration glue
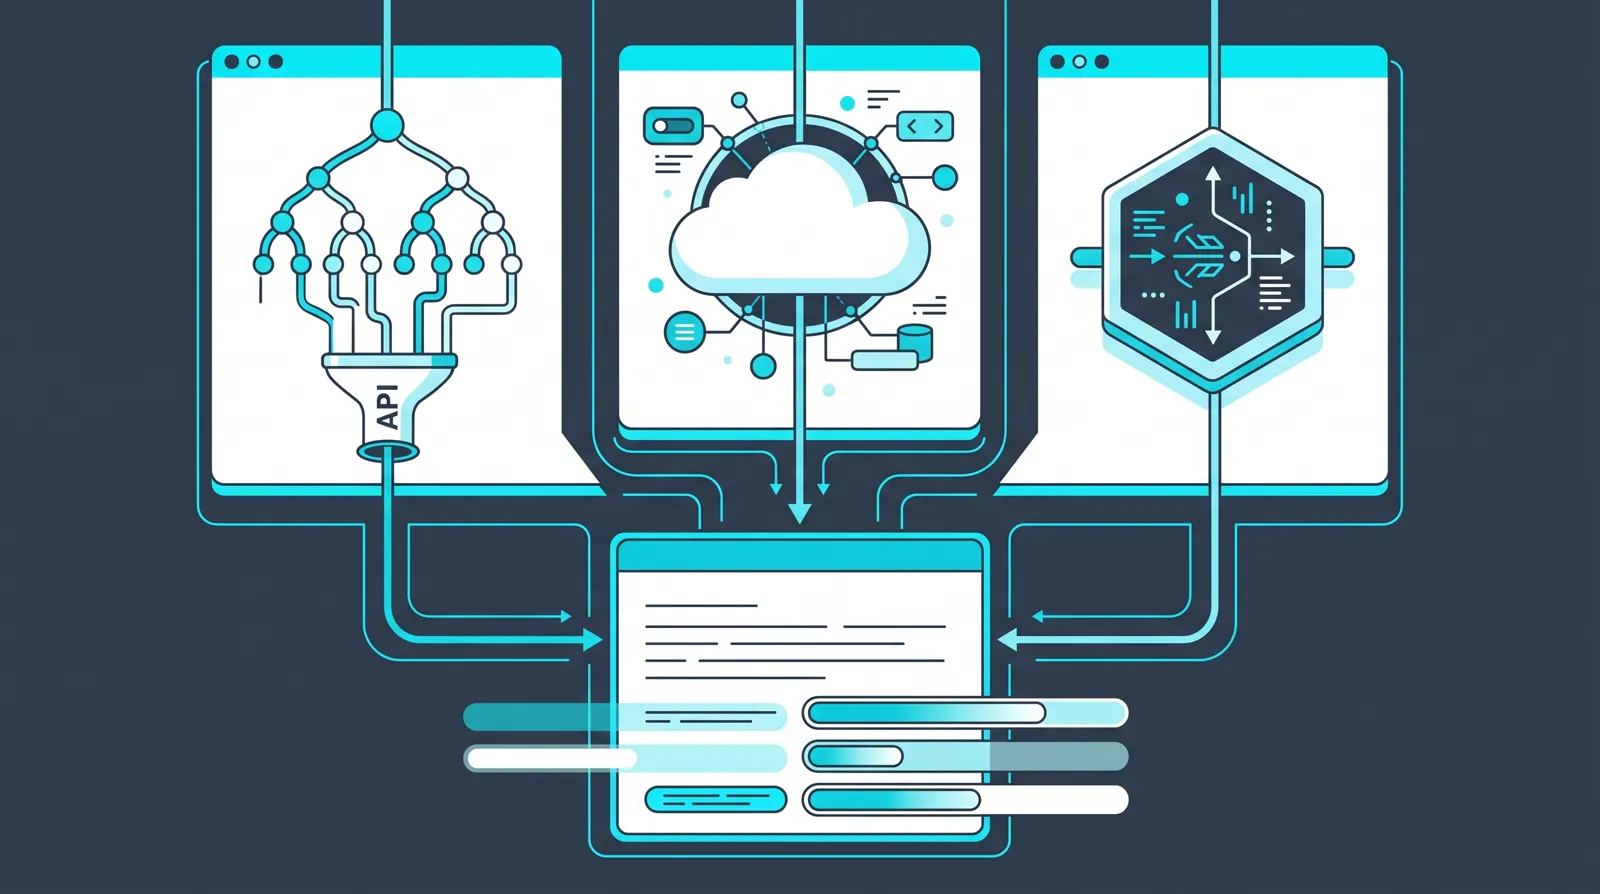
TanStack AI’s Evaluate API exposes one decide() contract and four adapters:
typesafeDecider('jev-latest')openRouterDecider('~typesafe/jev-latest')vercelGatewayDecider('typesafe-ai/jev')cloudflareDecider('typesafe/jev')
The state and question map stay put while the adapter changes. Credentials come from TYPESAFE_API_KEY, OPENROUTER_API_KEY, AI_GATEWAY_API_KEY or Vercel OIDC, and a Cloudflare Worker binding or account-and-token pair. This is useful for provider comparisons and failover experiments, provided the experiment records the resolved model and normalizes the response metadata. A shared function signature is not proof that four deployments behave identically.
Four open projects, none of them TypeSafe’s Jev
The open-source work is where the Jev ecosystem gets more interesting, and where names require care. These projects reproduce an interface or an inferred mechanism. They do not publish TypeSafe’s private weights or recreate its claimed RLCD training system.
LitJev is the zero-training route. It wraps off-the-shelf Qwen Hugging Face checkpoints, scores typed choices directly, and returns probability distributions without generating answer text. Its README calls the work a hypothesis-based reproduction and says probabilities are not calibrated by default. The code is Apache-2.0. That makes LitJev a useful local experiment, not a calibration claim.
openjev uses Gemma 3 4B for one-pass option scoring. It processes the shared prefix once, expands the KV cache across an option batch, and applies a softmax to the option scores. There are MLX paths for Apple silicon and PyTorch paths elsewhere, plus a FastAPI server with /v1/systemone and /score routes and a Doom demo. The MIT-licensed project is best read as a local scorer and research stack.
Kev is shaped most like a drop-in family. It is based on Qwen models and the mechanism described in Archer Hume’s “Jev’s Architecture Unmasked,” serves a System One-compatible endpoint with python -m kev.serve, and can sit behind the TypeSafe Python SDK. Kev is not Jev. Its original 0.5B checkpoint is explicitly marked as a superseded research prototype and not intended for production decisions affecting people; newer checkpoints now form the active family.
NanoJev takes the train-it-end-to-end route at roughly 0.6B parameters. It supports parallel decisions, dynamic Choice candidates from 2 to 255, Boolean questions, and ordered scores. The Hugging Face model is C-Tianyu/NanoJev, with unified-games-v1 naming its selected game checkpoint. Small and inspectable is valuable. It is still toy and research scale.
Open weights answer questions that a hosted endpoint cannot: Can the scoring mechanism run locally? What breaks under option reordering? How does a tiny backbone behave outside its training sources? They do not inherit TypeSafe’s calibration story by association. Each needs its own labeled evals.
When Jev should not get the job
Do not use Jev to write an email, generate code, hold a conversation, produce a report, or explore an open-ended plan. It returns decisions, not free text. A conventional language model is the right System Two component for work whose output space cannot be declared in advance.
Jev also needs a bounded schema. Choice accepts at most 255 options. Beyond that, reduce the candidate set first or use the two-stage score-then-choose pattern from the Doom and Wikiracing installment. If the correct answer may be absent from the list, add an explicit abstain or escalation path. Otherwise type safety can force a tidy wrong answer.
Schema validity is not safety. Jev can select only a permitted tool and still select the wrong one, confidently. High-impact payments, deletions, permissions, and external messages need deterministic checks plus a human route where appropriate. The guardrails installment covers that boundary in detail.
Finally, resist provider demos as production evidence. The published price and latency make Jev attractive for frequent routing, as the speed and cost analysis showed. Early access limits, model aliases, provider wrappers, and your own error costs can change the result. Run labeled traffic, choose thresholds from false-positive and false-negative costs, then monitor drift.
The series ends at a useful boundary
Day 1 started with Choice, Score, and Noul in working code. Six posts later, the durable idea is smaller than the launch hype: put a fast typed decision layer beside an LLM, and let application code own the policy.
Use the LLM to search, reason, draft, and explain. Use Jev where the state is known, the question is narrow, the answer space is declared, and probabilities can drive a measured threshold. OpenRouter, Vercel, Cloudflare, and TanStack have made that layer easier to reach. LitJev, openjev, Kev, and NanoJev have made its mechanics easier to inspect.
Access is easier. Judgment still is not.
