What OpenAI actually released
The OpenAI math results release contains 722 AI-generated manuscripts arranged into 372 result families. They came from an unreleased internal model, and many, though far from all, have linked Lean formalizations. The papers have not passed conventional peer review, while the independent AGMAI release rules are met only in part. That makes this a serious mathematical event and an unfinished audit at the same time.
OpenAI published the collection at 6 p.m. EDT on October 6, or 01:00 on October 7 in Türkiye. Its announcement describes “a broad range of new mathematical results” and says the company drew on advice from the Advisory Group on Mathematics and Artificial Intelligence at the Institute for Advanced Study. AGMAI’s own October 6 statement calls the release important, then adds two useful brakes: its advisory role is neither a judgment of the results’ impact nor an endorsement of the process, and publication only starts the work of human understanding.
That is the right reading frame. A public proof can be checked, challenged and repaired. A folder count cannot tell us whether 372 families will survive expert attention.
What is in the repository
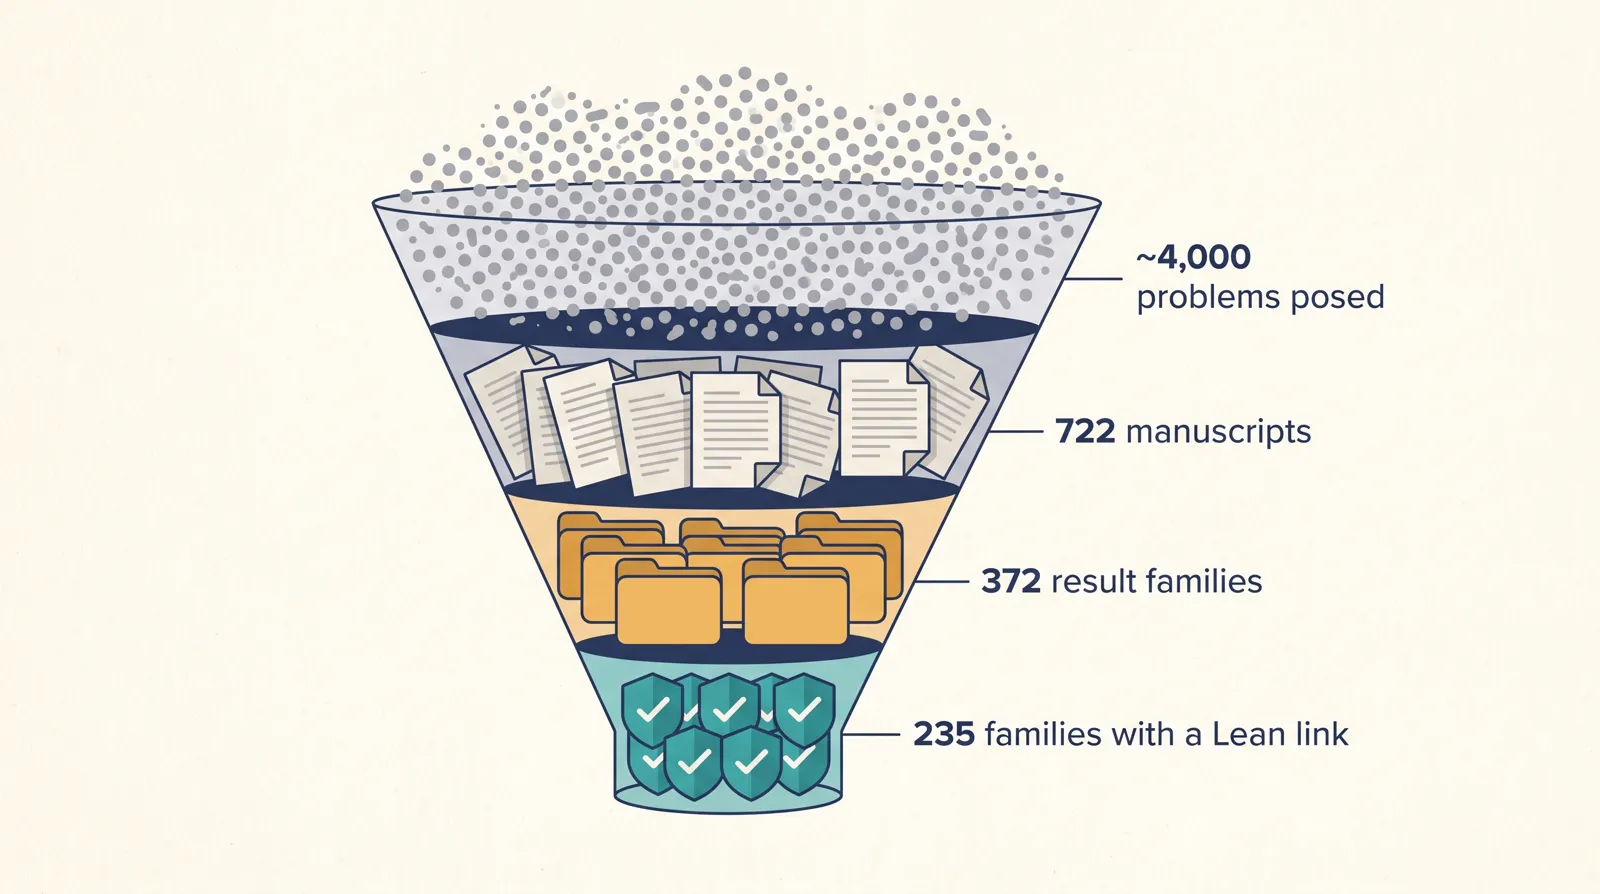
The repository README defines a family as a principal result together with companion arguments, consequences or alternate proofs. OpenAI says its existing mathematics evaluations had saturated, so it expanded the evaluation and posed approximately 4,000 problems to the model. The catalog emerged after outputs were aggregated and an “appropriate level of significance” was required.
The funnel therefore runs from about 4,000 posed problems to 372 families and 722 manuscripts. By my count of CONTENTS.md and formalization.yaml on October 7, 235 families carry a Lean link in the manuscript map, about 63 percent. The formalization manifest separately lists 162 papers “with a formalized main result” and 185 Comparator challenge entries. Those figures measure different units, so treating any one of them as the number of verified discoveries would be misleading.
The manifest is unusually candid. Its scope is marked “Partial progress”, review status is “unchecked”, and the automation method is “agent”. The Lean work builds on mathlib4, PrimeNumberTheoremAnd and other community libraries. Comparator, from the Lean project, checks a submitted proof against a challenge statement.
Dates in the manuscript paths cluster on September 23-25 and October 4-5. The repository also contains ten reasoning summaries, covering families 007, 017, 087, 102, 159, 197, 221, 271, 287 and 362. OpenAI reports an average result used compute equivalent to roughly three hours of ChatGPT Pro thinking. An average across the catalog is thin provenance for an individual theorem.
There were exceptions to the standard procedure. The zero-free-region work for the Riemann zeta function and the rational Hodge result for CM abelian varieties did not follow the fixed process, and the write-up for the Re(s) > 11/12 region was edited by a human for readability. Corrections will appear as new versions while old ones remain available, and every manuscript gets BibTeX. Those are useful publication mechanics.
How to read the OpenAI math results through Lean
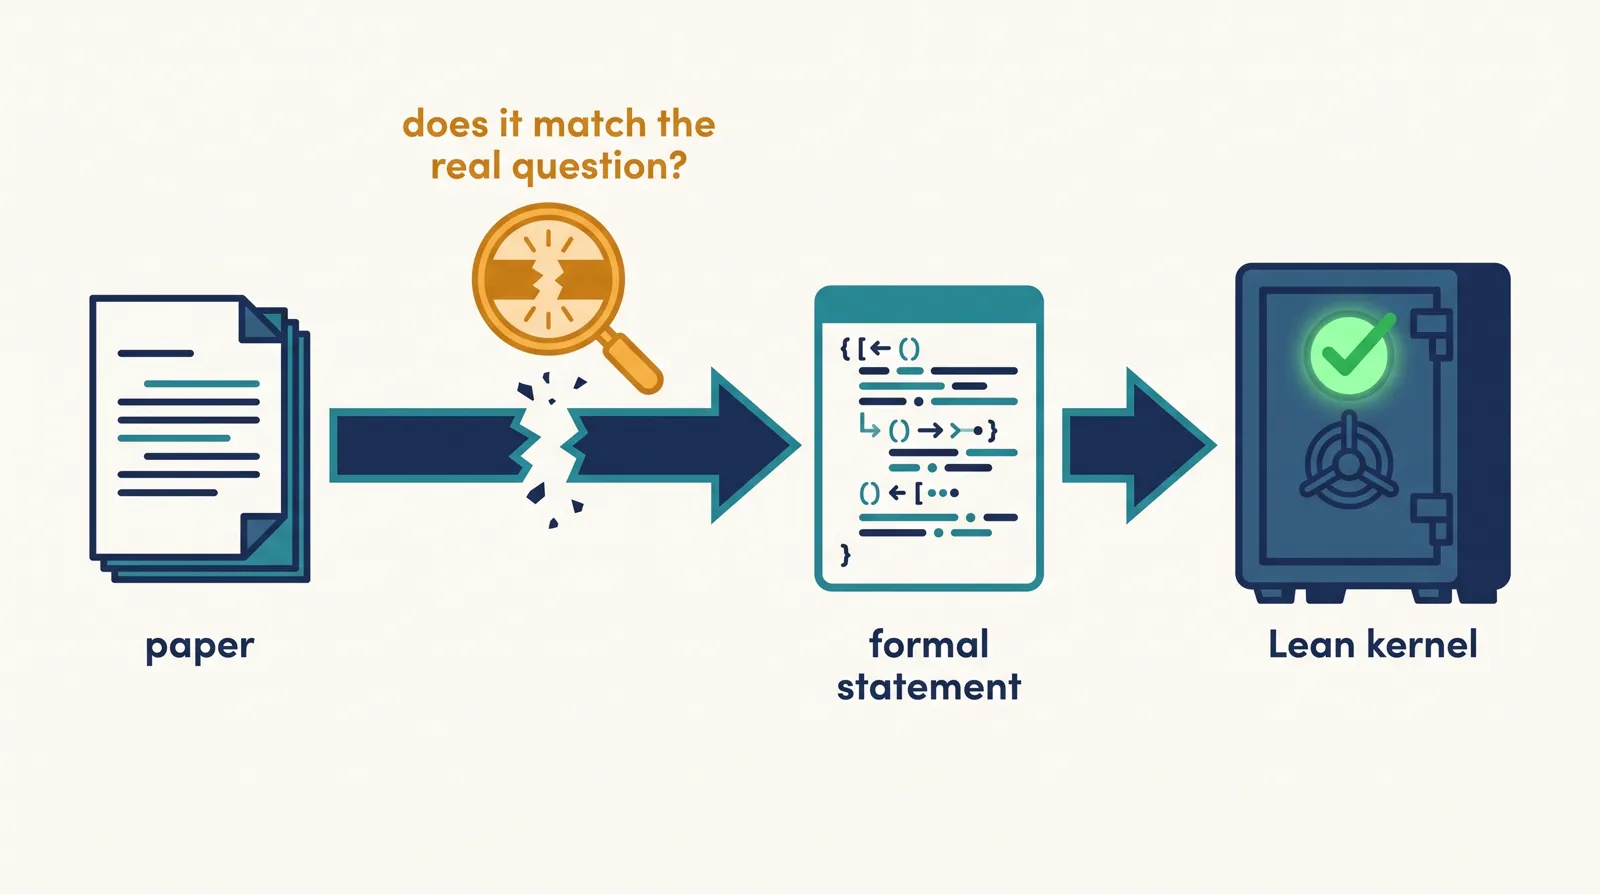
Lean can establish that a formal proof term checks against a formal statement, given the stated libraries and trusted kernel. Comparator adds a practical comparison between the challenge statement and the supplied proof. If independent users rebuild the files, they gain strong evidence that the machine-encoded theorem follows within that environment.
One hard question sits before the kernel: does the formal statement faithfully represent the mathematical problem people care about? Lean cannot decide whether a hypothesis quietly narrows the original question, whether the theorem carries the importance claimed for it, or whether the exposition gives humans a useful idea. And for the 137 families that have no Lean link at all, by my count, there is no formal check to lean on in the first place.
The September Navier-Stokes dispute is a clean worked example. OpenAI’s September announcement concerned a finite-time singularity for an initially smooth fluid at rest under a smooth applied force. The company claimed Clay statements C and D and explicitly declined to claim the Millennium Prize. The construction used a swarm of about 10,000 agents over 88 hours, unlike the mostly single-agent process described for this release.
The distinction between forced and force-free equations changes the question. Our September 22 digest on the forced versus force-free clause covered the resulting argument. A flawless formal proof of the forced statement would still leave the famous unforced problem untouched. Family 376 in the new repository, “Universal computation in forced Navier-Stokes flows”, makes its external force explicit. This is precisely why formal correctness and claim matching need separate checks.
Scientific American’s report says Lean-verified results are all but certain to be correct. I would add five words: relative to their formal statements. The qualification is small on the page and large in mathematics.
A scorecard against AGMAI’s release rules
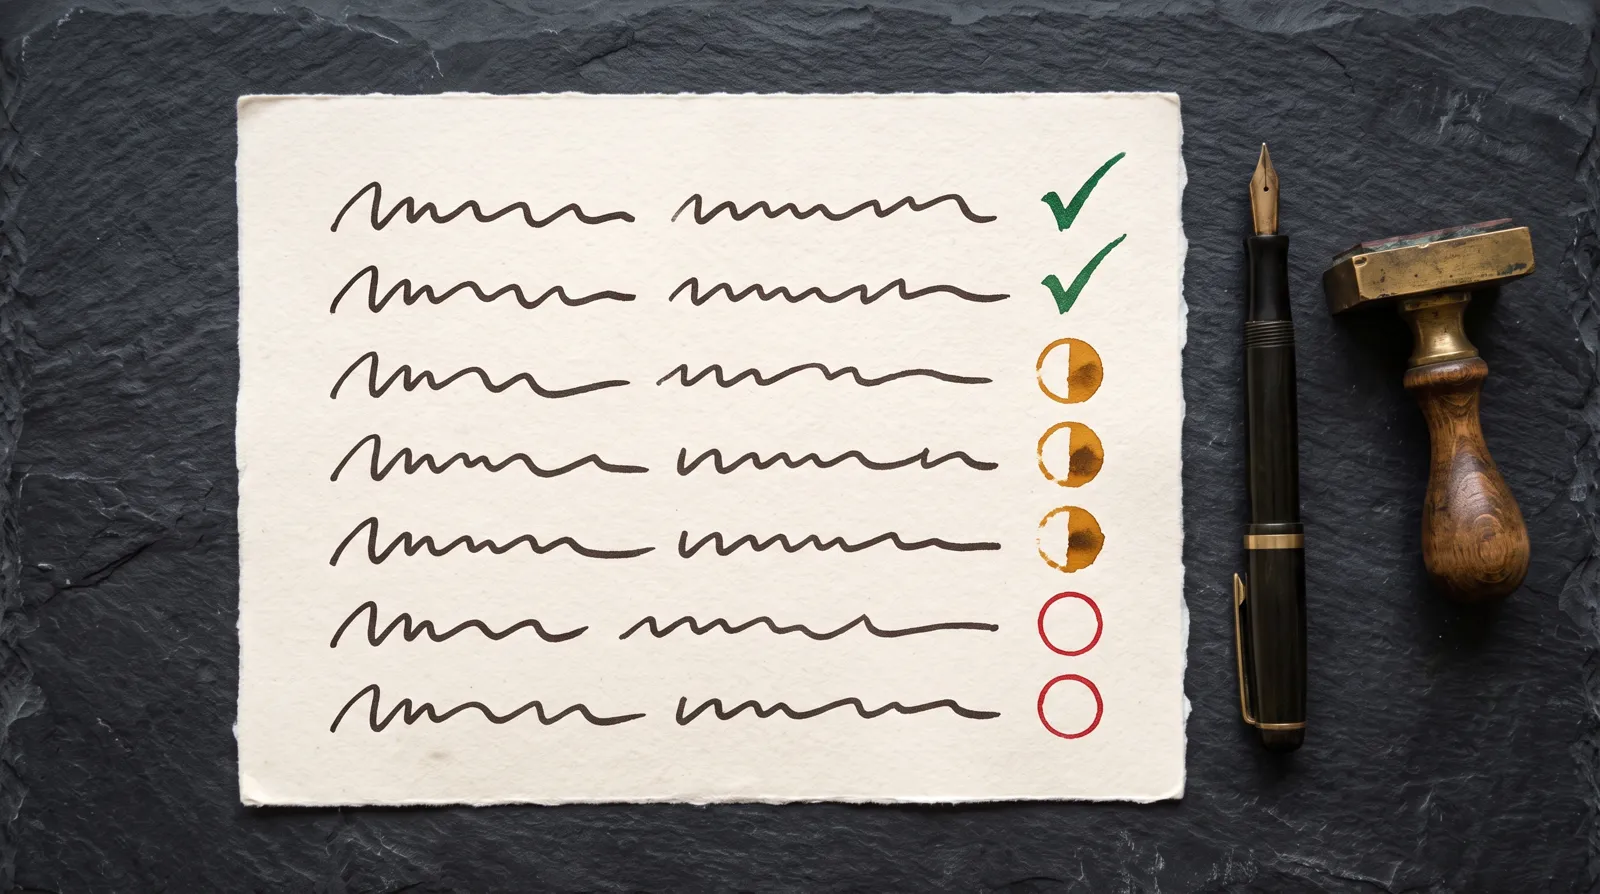
AGMAI was formed independently after OpenAI approached some mathematicians about an external advisory board. Its nine unpaid members are François Charles, Camillo De Lellis, Timothy Gowers, Martin Hairer, Nikhil Srivastava, Ulrike Tillmann, Ravi Vakil, Edward Witten and Melanie Matchett Wood. More than 600 survey responses informed its September 29 recommendations. The group asks labs to stop testing advanced problems on proprietary models and warns against using mathematical releases as model marketing. Here is my point-by-point reading:
- Rule 1(a) and 1(b), literature and traditional papers: OpenAI supplied manuscripts, citations and revision machinery. Yet the company says citations, exposition and presentation need improvement in future releases, and Scientific American reports that many results are not yet understood by OpenAI’s own mathematicians. Verdict: partly met.
- Rule 2, an independent scholarly repository: The files live under OpenAI’s GitHub organization, which the lab controls. Version history and BibTeX help, and OpenAI says it is exploring community-hosted alternatives with the required features. Persistent scholarly identifiers and an independent home have yet to appear. Verdict: not met yet.
- Rule 3, per-result provenance: AGMAI asks for the model name, prompts, summarized chain of thought, time and estimated compute cost for each result. The model is unnamed and unreleased. There are no prompts, ten reasoning summaries for 372 families, and only an average compute figure. A spokesperson told Scientific American that OpenAI does not consider itself bound by the recommendations. Verdict: not met.
- Rule 4, formalize as far as possible: The repository has Comparator challenges and a
formalization.yaml, with status labels that admit partial and unchecked work. The Lean files I opened carried no copyright headers, which AGMAI also asks for. About 63 percent of families have a Lean link, while 162 papers are listed as having a formalized main result. Verdict: largely met for a subset. - Rule 5, disclose selection and failures: OpenAI gives a denominator of roughly 4,000 posed problems and says the evaluation expanded after older benchmarks saturated. It does not give a full account of problem selection or comparable failed attempts per family. Verdict: partly met.
- Step II, fund human understanding through existing nonprofits: OpenAI promises workshops, conferences and special programs, with details later. The decision mechanism and role of existing nonprofits are unknown. Verdict: promised, not yet assessable.
- Broad, equitable access: AGMAI warns of a two-tier system built around proprietary internal models. OpenAI says it is working toward a responsible release, but the producing model remains unavailable. Verdict: not met.
On the marketing point, one data point is enough for readers to judge: Sam Altman’s post on X read “We are entering a new era of discovery now.”
The governance issue is familiar: who evaluates AI when the lab grades itself? AGMAI gives the public a concrete checklist. Its own refusal to endorse either process or impact keeps that checklist independent.
The headline claims, read carefully
Family 102 claims a proof of Khot’s Unique Games Conjecture through a deterministic polynomial-time reduction from 3SAT to unique games with a value gap. It also claims optimal Max-Cut hardness beyond Goemans-Williamson and factor-two Vertex Cover hardness. The Lean note says the formal statement does not build in a P ≠ NP assumption. That detail matters when translating formal hardness into the familiar conditional language.
Family 107 gives ω(ℂ) ≤ 9/4, or 2.25, over the complex numbers for square matrix multiplication and ω(F) < 2.371054886006746 over every field. Its Lean documentation expressly concerns arithmetic complexity, without a claim about bit complexity or practical crossover sizes. Your GPU does not become faster this morning.
Family 003 establishes a zero-free half-plane Re(s) > 7/8 for the Riemann zeta function, every Dirichlet L-function and finite-order Hecke L-functions over Q(√-3). A companion gives Re(s) > 11/12, plus a uniform Landau-Siegel exclusion without an explicit constant. The Riemann hypothesis requires the critical line Re(s) = 1/2. Calling this an incomplete proof of RH, as some Reddit threads did, muddies a substantial analytic-number-theory claim.
Elsewhere, family 074 claims the three-dimensional Kakeya maximal conjecture and the four-dimensional Hausdorff-dimension Kakeya conjecture. Family 032 covers the rational Hodge conjecture for every complex CM abelian variety, with the procedural exception already mentioned. Family 376 builds a Turing-machine compiler into the external force for Navier-Stokes flows. Big claims, different shapes, different caveats. "Hundreds of open problems solved" compresses all of that beyond usefulness.
The wider concern did not begin yesterday. Our September 13 digest covered the "A Severe Misalignment of AI in Mathematics" statement signed by 25 Fields Medalists.
Who said what
Scientific American's report captures the split. MIT's Andrew Sutherland said claims of solving problems in one shot with one agent should remain unverified until the model is released and others can replicate the results. Daniel Litt of the University of Toronto argued that if mathematicians want the answers, keeping them secret would serve no purpose and publication should benefit mathematics.
Terence Tao has criticized the "insane" pace of frontier-lab output. Writing on Mastodon on October 6, he observed that a solved problem cannot become unsolved again and that knowing a solution exists changes later human and machine attempts. His proposed "Math 2.0" would value mathematical progress more broadly than raw problem solving. Steven Strogatz compared the jump in the matrix multiplication exponent from roughly 2.37 to 2.25 with Bob Beamon's long jump. Joe Bebel noticed a claimed proof and Lean formalization of Unique Games, a problem he said he had worked on for a year and a half. Jared Duker Lichtman called the output "absolutely historic by any objective metric", then added that it was not the Millennium-problem result rumored in previous weeks. Enthusiasm and inspection can coexist.
What would change the picture
Release the model, or provide broad access under terms that permit replication. Publish exact prompts and per-result attempt histories. Move the manuscripts into a community repository with persistent identifiers and durable version records. Then let independent teams rebuild every Lean artifact from a clean environment and compare each formal statement with the original problem.
Human referee reports matter next, especially for the families without formalization and for claims whose significance depends on specialist context. Funding can help, provided existing nonprofit institutions choose the workshops and programs as AGMAI recommends. OpenAI's promised support has no public mechanism yet.
The repository has created inspectable work. It has not supplied enough provenance to validate the story of how that work was produced, and the formal checks cover only part of the catalog. For now, read theorem by theorem. Mathematics has always been slow at the point that counts: other people must understand the proof.
Sources
- OpenAI: Sharing AI progress in mathematics
- OpenAI mathematics repository
- AGMAI recommendations, September 29
- AGMAI statement and group information
- Scientific American: OpenAI releases hundreds of math results
- OpenAI: September Navier-Stokes result
- Techmeme roundup of reactions (Strogatz, Bebel, Lichtman, Tao, Altman)
